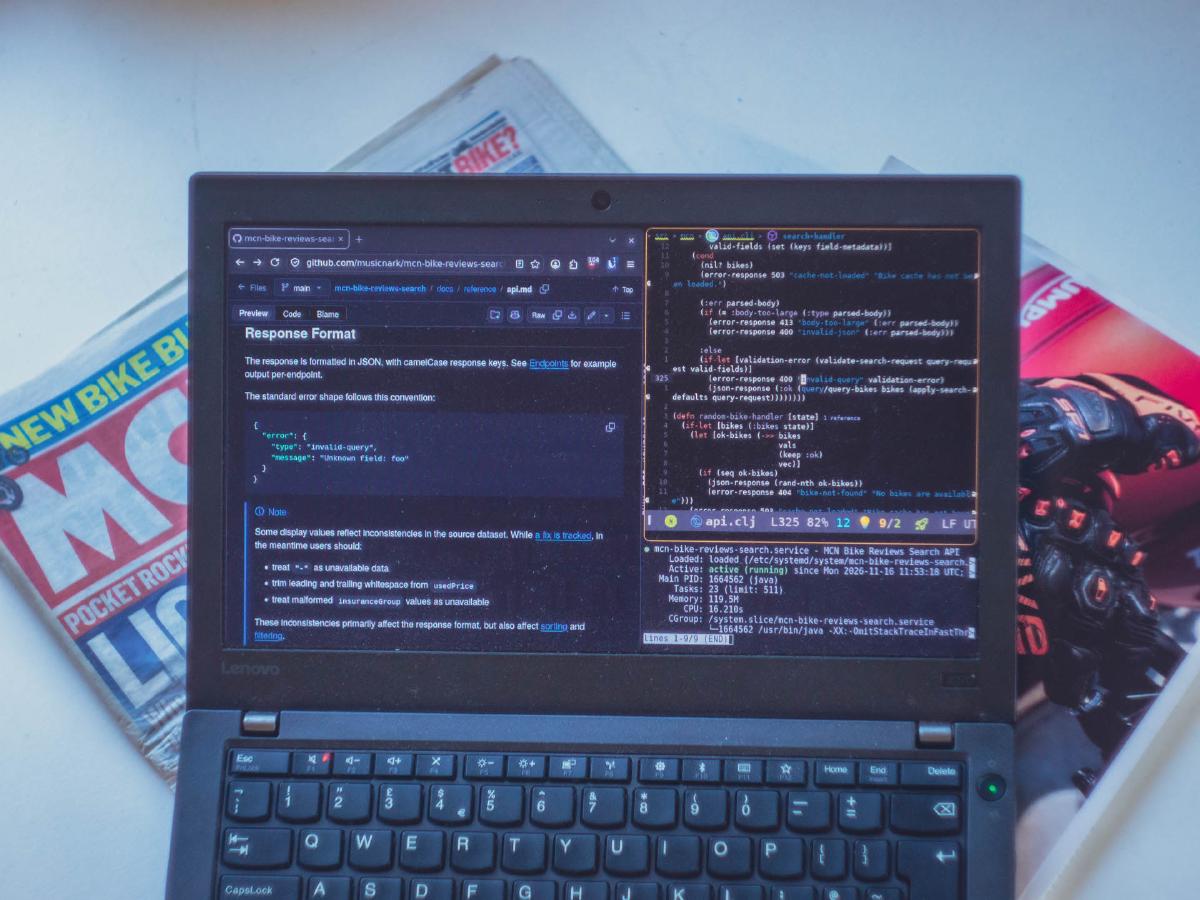
While I was working at Motorcycle News as a product writer, I encountered a number of workflow bottlenecks that were losing time. After my first workflow automation tool was fully integrated into the team workflow, internal tooling became part of my regular duties. This is the largest and most recent tool I made for the editorial team — MCN Bike Reviews Search.
The Workflow Problem
MCN has one of the largest single archive of motorcycle reviews on the internet (if you know, you know). It's one of MCN's greatest digital assets, with long-tail organic traffic, and it's a gold mine of potential content ideas. That is, if you can search the bike reviews effectively.
A rudimentary archive search existed, but there was no way to filter bikes by their specs, like:
- seat height
- engine power
- used price
- fuel economy
- running costs
- etc
Research meant opening individual review pages and manually checking for bike specs, and that was taking hours per week of editorial time.
My pitch was simple. With one well-structured query, you can immediately find all the "Best Bargain Bikes for Speed Demons", or "Most Fuel-efficient but Motorway Capable Bikes" for whatever newsletter, buying guide, or social post you're currently working on. Or, if you're tasked with generating new content ideas, your source of inspiration should almost never run dry.
I prototyped a working demo within 24 hours, pitched it to editorial and IT teams, and gained their backing to develop it into a full version.
Why I Built an API, Not Just a Spreadsheet
After a lot of deliberation, I decided an API really was necessary for this tool. MCN were sitting on a potential gold mine, and it was my job to extract the most value out of it. Building an API out of it was the approach I decided, for a few reasons.
First, it could become reusable infrastructure — not just a one-and-done tool. A well-designed API gives a predictable way to query for other interfaces, scripts, AI agents and more. That makes future features or integrations much quicker to develop, and the value proposition compounds over time. In a large publishing environment, where systems often grow in isolation without talking to each other, that matters — it was the single biggest source of user complaints while I was there, hindering workflows for many moons before my arrival. My single API could act as that one small step for MCN, but a giant leap for publishing-kind.
As well as this, the data we needed wasn't useful as plain text — only when queryable by attributes. Making associations between data points was a big part of the value the tool promised, so it needed to be stored as structured data. Keeping data structured also meant it could be truly portable — readable by any tool for any purposes. The option to add features later for different kinds of search was crucial, as there are always new use cases to be discovered, and I wanted to keep those options open by design.
Motorcycle specs also needed to be filterable, sortable, and comparable, which warranted a tool with its own query engine.
So with that decided, I got to work implementing.
Turning Messy Pages into Structured Data
The first major problem I encountered was actually getting to the data. All the entries already existed in a MySQL database, but as an editorial colleague I wasn't given access to it directly. So, I thought if I can't get in through the back end, head to the front.
Inspecting HTML from the live web pages, the bike specs were rendered as HTML table elements. It looked quite straightforward at first — fetch the pages, parse the tables with CSS selectors, and normalise the results.
But the real work was making that process reliable. I had to handle sitemap extraction, async page fetching and parsing, rate limiting, retries, error handling, and cached records.
The main hiccup with parsing came down to the age of the archive. Motorcycle review pages have been through several different formatting changes over the years, so one parser had to handle multiple generations of page structure.
Failures had to be kept inspectable, so I paid particular attention to errors around the system boundary and wrapped them with relevant metadata. That meant HTML fetch errors could retry automatically, and HTML parse errors wouldn't block the rest of the pipeline.
Once the pipeline could generate cached records reliably, the first hurdle was complete. It was now ready to support the query engine.
Designing the Query Shape
Before the API could start being useful, it needed a query shape that mirrored the questions writers were actually asking. I felt a request like "find me some short, cheap bikes" shouldn't require a unique endpoint or a mass of query-string parameters — it should be representable as structured data. So, that's how I designed it.
The smallest useful query is a comparison against one known field:
{
  "filter": {
    "type": "comparison",
    "field": "seat-height",
    "op": "<",
    "value": 800
  },
  "limit": 10
}
In a nutshell, this means:
"Find all the bikes with a seat height below 800mm, and show me the top 10 results"
The field names are deliberately explicit, to make them as self-explanatory as possible.
With this, you can send a query to the live API; e.g., with curl:
curl -X POST https://labs.musicnark.com/mcn/api/bikes/search \
  -H 'Content-Type: application/json' \
  -d '{
    "filter": {
      "type": "comparison",
      "field": "seat-height",
      "op": "<",
      "value": 800
    },
    "limit": 10
  }'
Although that's useful on its own, the real value comes from condition combinations. A writer may want to find bikes with a low seat height and a used price below £2,500, and maybe they want to sort by price not seat height.
So, instead of creating a new endpoint for nested queries, we can wrap each comparison in an and filter:
{
  "filter": {
    "type": "and",
    "clauses": [
      {
	"type": "comparison",
	"field": "seat-height",
	"op": "<",
	"value": 800
      },
      {
	"type": "comparison",
	"field": "used-price",
	"op": "<",
	"value": 2500
      }
    ]
  },
  "sort": {
    "field": "used-price",
    "direction": "asc"
  },
  "limit": 10
}
In this instance, and is just another type of filter node that contains more filters.
The request is still fairly readable, but it describes a more useful question:
"Find all the bikes with a seat height below 800mm and a used price below £2500. Show me the top 10 results, sorted in ascending order by their price."
At that point, a curl request looks like this:
curl -X POST https://labs.musicnark.com/mcn/api/bikes/search \
  -H 'Content-Type: application/json' \
  -d '{
    "filter": {
      "type": "and",
      "clauses": [
	{
	  "type": "comparison",
	  "field": "seat-height",
	  "op": "<",
	  "value": 800
	},
	{
	  "type": "comparison",
	  "field": "used-price",
	  "op": "<",
	  "value": 2500
	}
      ]
    },
    "sort": {
      "field": "used-price",
      "direction": "asc"
    },
    "limit": 10
  }'
This same structure supports or, for cases where any of several conditions can match, and not, for excluding bikes that match a set of conditions.
That gives the API a small query language:
comparisonchecks one field against one value.andrequires every child filter to match.orrequires at least one child filter to match.notexcludes anything matching its child filter.
I decided to keep sorting and the results limit separate from the filter, as I felt that for this use-case they're both most useful when acting on the entire result, as opposed to each individual filter.
I also added an /api/fields endpoint that lists each field name, so a caller can discover them interactively. You'll find fields such as seat-height, used-price, max-power, etc, along with their data types and units of measurement — so a caller knows what fields can exist before it receives any result.
As far as query languages go my implementation is quite narrow, as comparison filters only currently support numeric fields. As much as that is a limitation, it was a judgement call I made to limit the initial scope of the API — string match filtering is only useful for niche cases like finding bikes with "Brembo" branded brakes specifically. On the other hand, numeric comparison is critical to almost every search.
Ultimately, I wasn't trying to build a mini version of SQL. The goal was to give editorial tools a standardised way to ask useful questions about the archive. A writer, script, automation or AI-assisted workflow could construct a query from the same small set of parts, and the API would respond the same way to every caller.
There was one caveat to making the filters composable though. Once a request can contain nested objects, arrays and multiple possible filter types, the server can't safely pass arbitrary JSON straight to the query layer.
Making It Safe Enough for Other Systems to Call
Now the API needs some guardrails — it should know which fields and operators are valid, how deeply filters can be nested, and how much work a single request is allowed to ask for.
Validation
Making sure a query can technically be run before actually running it is crucial for any long-standing API. It improves performance for your users while also keeping the bad guys out. So, I categorised the common failure modes and built validation for them into the API.
Malformed JSON
It's easy to forget, but mistyping causes some of the biggest and most needless errors, So I made sure that a query is only run if it contains valid JSON.
Unknown Fields
Since all the potential fields are already defined, it was easy enough to check the incoming query to make sure all fields are valid.
Clause & Nesting Depth Limits
These could be a ripe avenue for a denial of service attack, as otherwise you could send a query with billions of clauses, or trillions of filters. Without protections built in, a caller could have your API running in circles chasing its own tail-call optimised stack overflow.
There are only a handful of expected clauses in any given instance for this API, so I set a generous 25 maximum clause limit, to give some headroom or extra clauses to be added. Similarly, if there's more than 10 levels of nesting in any given filter, a query gets rejected.
Oversized Bodies
We can't let a billion-line long JSON query past the door no matter how nicely it follows our other rules. My AWS bill can't handle it. So less than 65,537 characters, or you're out.
Structured Errors
If anything does go wrong in one of these expected ways, you'll get a clear response from the API explaining why. For example, if you try to filter by an invalid field:
{
  "filter": {
    "type": "comparison",
    "field": "not-a-field",
    "op": "<",
    "value": 800
  }
}
The response is:
{
  "error": {
    "type": "invalid-query",
    "message": "Unknown field: not-a-field"
  }
}
I was using the bind pattern for error handling internally within the codebase, and it mirrors well to the kind of structured error you'd expect from an API.
Health Checks
It's good practice to check an API is up and running before attempting a query, so I added a api/health endpoint for this purpose:
{
  "status": "ok",
  "cacheLoaded": true
}
It's short and to the point, but it doesn't need to be anything more.
From API Endpoint to Editorial Workflow
At this point we have a safe, featureful, and functional API. But, it's still an API, and that's a big problem. Writers don't use APIs, they use GUI tools like WordPress. That's ultimately who I was building this for.
For this reason, a front-end for the API was a high priority for this project. However, as a stop-gap to make the tool usable by non-technical writers while I was still working on the front-end, a new challenger approached…
I made a custom AI agent within our company's own ring-fenced LLM of choice. At first it was designed just to translate a natural language request into an API valid JSON query, and at that job it was quite frankly stupendous. But it ended up being really good at more than just that.
Interactive Tutorial
As I started experimenting, I discovered it could be an interactive tutorial. So I added a feature that would explain how the tool works to the user, and give them a few examples to try in their next prompt. Because it has access to the docs for the tool, it has all the knowledge it needs to troubleshoot, and if there's anything a user doesn't understand they can just ask.
After that, onboarding users became a cakewalk, and I had more time available to build out the rest of the tool.
Idea Generation
It's not always easy to come up with ideas for content, and especially so when the deadline is sprinting right at you. So, I added a feature that would generate content ideas.
In terms of the implementation, it gets details for 10-20 bikes from the api/bikes/random endpoint, and finds any correlations between any of the bikes — similarities between style, brand, age, reviewer comments, etc. Then, it synthesises those into attention-grabbing headlines in line with MCN style.
I think it worked so well for this case because the LLM in question had already been trained on all of MCN's previous content, so it already knew almost intrinsically what kind of content could work. From there the world's your oyster — you can have features for first-draft generation, shortening a final draft for social media/email newsletter, etc.
LLM – API Interface
A full-on MCP server would have been overkill for this project, so the LLM interfaces with the API the conventional human way — read the docs, request the endpoints, format a user-facing response, rinse and repeat. It turns out that this is all that's necessary for this use case, but only because the API docs were comprehensive enough.
Documentation as Part of the Tool
The docs were an especially important part of the project because of this. In this case, the docs served as context for the LLM, so they had to be written with multiple readers in mind. That's why Diátaxis felt like such a natural fit — the LLM is just one of those readers.
The docs are split into four different sections; how-to, reference, concepts, and the docs root.
I decided to structure the documentation to serve the needs of the main audiences for the tool — editorial staff, internal stakeholders, technical implementors, and LLM tooling.
The structure was designed so that each section of the docs naturally draws in the audience most interested in it — like a coin sorting machine. Users should gravitate towards how-to guides, technical implementors will want to understand technical concepts, and stakeholders have a value proposition in the business-pitch. The docs root README then acts as the natural starting point linking out to the relevant sections, and I made sure that the reader journey from there made sense for each audience.
Why This Matters for AI Agents
In the world of AI agents, one of the hardest problems is trust — how can you be confident the agent will actually do what you asked it to?
Prompts alone aren't enough, as that quickly becomes a case of "be careful what you wish for" — and just like the genie in the bottle, an agent can turn your best intentions against you if it misinterprets your request, encounters a phantom error, or produces a result you can't verify.
An agent can only be as reliable as the systems it interacts with, so those systems need to have clear contracts, constrained inputs, predictable behaviour, and errors that genuinely explain what went wrong.
That was the main reason I built an API before adding the agent layer — the API provided a predictable, consistent, and verifiable foundation. Then the agent could translate a human request into a valid query, rather than having to be the query engine itself. Some stakeholders were initially unsure whether both layers were necessary, but a working demo made the value of dividing responsibility clear.
What I'd Improve Next
Although the tool is regularly used by editorial colleagues and incurs few maintenance costs, it's far from a perfect implementation, and there are a number of things I would improve.
Database
The most obvious improvement is to use a proper database instead of the local EDN cache. As outlined earlier, nothing more was needed for the scope of this project, but it certainly doesn't scale well. More advanced features would make good use of sequential writes, partial updates, versioning, and all the other features you'd expect from a proper database solution.
Authentication
This is an area that would be necessary for enterprise-wide adoption. In this case, all the data stored is publicly available, and keeping it open for everyone to access is one of my goals with the project. But an authentication token or API key would make it possible to enforce rate limits or usage quotas on a per-client basis, helping manage server costs should the tool ever be used by thousands of people per day.
Front-end
I had originally planned a front-end for this tool, and despite the AI agent assuming that role, I would still add a proper front-end to improve it. Results could be displayed in interactive cards, and users could amend the query manually through a "drag'n drop" interface for more granular control. As it stands, the AI agent integration serves the needs of the team well enough, but it was never meant to be a complete replacement for a front-end.
Observability
On the server side, I would want to implement better observability, particularly logging. Even just routing the existing error output to a log file would go a long way, but a more fleshed-out health endpoint with details such as uptime, last error, and other server status info would make the tool easier to monitor and debug.
CI/CD pipelines
Although I implemented a small CI pipeline for validating changes, a CD pipeline would help with automated deployment. As it stands, there's a guide in the docs that walks you through manually setting it up on a Debian VPS, which is enough for the scale of the project currently. But automated deployment would allow changes to move more quickly from development into a staging or production environment, while reducing the risk of mistakes during manual updates.
Test coverage
Although the test suite covers the core query, API validation, storage, retry, and utility behaviour, it doesn't exercise the complete data flow, and would need thorough expansion — the ingestion pipeline is the biggest gap here. I would add fixture-based parser tests, stubbed integration tests for the sitemap and refresh pipeline, API contract tests for every supported filter type and endpoint, and explicit failure-path tests for corrupt caches, failed requests, and partial refreshes.
Closing Lesson
When all was said and done, the hard part wasn't making MCN's Bike Reviews archive searchable — that was actually the easiest part.
The hard part was turning messy editorial knowledge into an interface both people and software systems could genuinely trust.
It meant combining technical implementation with product judgement and user experience, while keeping the tool simple to use, inspect, maintain, and debug despite its many interconnected parts.
It meant clearly communicating what the tool can do, what it can't do, why it's useful, and how it works to editorial colleagues, internal stakeholders, developers, and AI agents.
It meant making and defending design decisions, based on my experience working at the intersection of editorial and technical work, that served both needs.
It meant managing stakeholder expectations, holding the line against scope creep, onboarding and supporting users — all against a fixed deadline.
When you've been through an experience like that, you start to realise — the bottleneck was never coding.